GTX 1070 Passthrough on a PowerEdge T320: A GPU Node for Local AI
Choosing a card a tower server can power, validating it on the host, then binding it to VFIO and handing it to a dedicated inference VM.
work: Apr–May 2026 · Done · CyberDen, AI, Proxmox, GPU, HardwareWhy
The T320 had cores and RAM (10c/20t Xeon, 96 GB ECC) but no GPU, so local models crawled on CPU. I wanted an always-on inference node inside the lab, isolated in its own VM, so AI experiments don't touch the hypervisor.
Choosing a card the server can feed
The T320 wasn't built for gaming GPUs. The limits were PSU capacity, how to get 6/8-pin PCIe power from a server PSU, and physical fit. I went through used listings (RX 580, GTX 1650 Super, 1660 Ti, GTX 1080, a Quadro) and a $100 mixed hardware lot. The lot's GPUs turned out to be low-end cards with no compute value.
I picked a GTX 1070 8 GB: Pascal, CUDA-capable, 8 GB VRAM, at a power draw the server could supply through a PSU adapter.
Proving the hardware first
Before any passthrough I confirmed the card was healthy on the host:
lspci -nn | grep -i nvidia   # GP104 [GeForce GTX 1070] [10de:1b81]
dmesg | grep -i -e aer -e pcie   # no AER errors, no link failures
sensors                           # temps normal
stress-ng --cpu 4 --timeout 60s   # load test while watching power
No AER errors or PCIe link failures under load meant the adapter and cabling were stable. The host had loaded nouveau, which is fine for detection but useless for CUDA.
Passthrough, host side
- Enable IOMMU in GRUB and reboot:
GRUB_CMDLINE_LINUX_DEFAULT="quiet intel_iommu=on iommu=pt"then
update-gruband checkdmesg | grep -e DMAR -e IOMMU. - Identify both functions of the card (VGA and HDMI audio). They pass through together.
- Bind them to
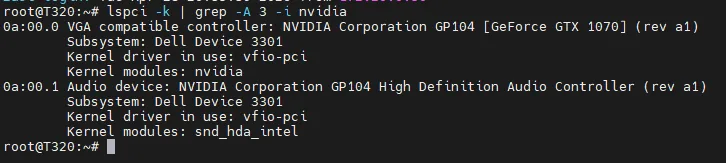
vfio-pciby ID and blacklist the host drivers. - Confirm:
Kernel driver in use: vfio-pciThe host is no longer using the GPU; it's holding it for a VM.
Passthrough, VM side
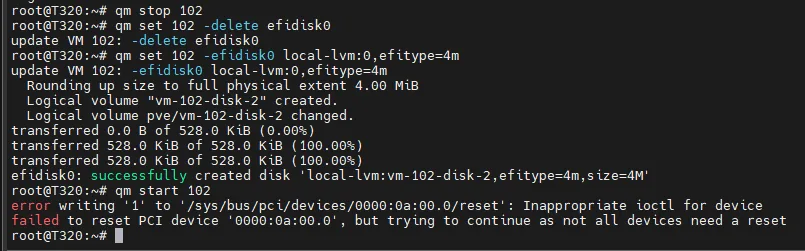
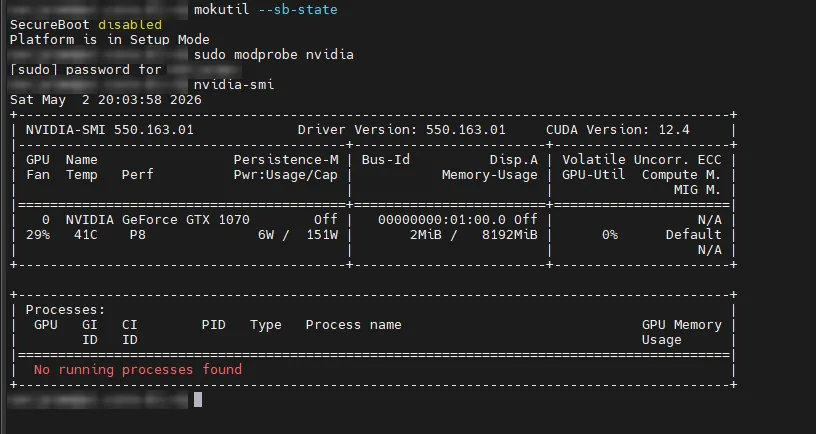
ai-core-01: q35 machine, the GPU added as a PCI device (all functions, PCIe)- Inside the VM: install the NVIDIA driver, reboot, run
nvidia-smi, and the GTX 1070 shows up - Run a model and
watch -n 1 nvidia-smi. If GPU utilization jumps, inference is on the GPU.
Results and limits
The VM now has the GPU to itself. 8 GB of VRAM means 7–9B quantized models fit fully; larger ones spill to CPU. Pascal has no tensor cores, so it's a learning and lab node, not a training rig. I'm already looking at what it would take to power a second card.
Lessons
- Validate power and PCIe health before blaming drivers.
- Pass the whole device: video and audio functions together.
- One GPU, one VM. Isolation is the point. The hypervisor shouldn't run AI workloads.
Sources: CyberDen Flip Breakdown (27 Apr 2026), Local AI LLM Setup (27 Apr 2026), Increase T320 GPU Power (10 Oct 2026), T320 GPU Compatibility (10 Oct 2026)